# Sequential Diagnosis with Language Models
An interesting study on longitudinal diagnosis
Canonical: https://astro-blog-bice-chi.vercel.app/blog/sequential-diagnosis
Edition: en · Language: en · Revision: 1
Archived: 2025-07-22
Updated: 2026-09-21
The archive date records this article’s first appearance in this repository; its original publication date is unknown.
Identifiable source figures and tables were re-extracted from pinned paper versions. Original attachment files remain unavailable; uncertain matches are explicitly marked. Selected source and metric descriptions were corrected.
Updated 2026-09-21
### Sequential Diagnosis with Language Models
Published Jun 2025
URL [https://arxiv.org/pdf/2506.22405](https://arxiv.org/pdf/2506.22405)
Tags
EvaluationMulti-AgentDiagnosis
## [Takeaways](https://astro-blog-bice-chi.vercel.app/blog/sequential-diagnosis#takeaways)
1. An interesting setup for testing the **DIAGNOSTIC ABILITY** of LLMs.
2. OpenAI’s O3 performs **VERY WELL** in this simulated diagnostic benchmark.
3. Claims on cost/superiority over humans should be taken with a [grain of salt](https://astro-blog-bice-chi.vercel.app/blog/sequential-diagnosis#criticisms).
## [Method](https://astro-blog-bice-chi.vercel.app/blog/sequential-diagnosis#method)
* 304 New England Journal of Medicine clinicopathological conference (NEJM-CPC) cases.
* 56 most recent cases as a held-out test for generalization.
* **VERY CHALLENGING** and **SELECTED**: Published diagnostic puzzles, rather than a representative sample of routine patients.
* Build a “gatekeeper” as a simulated environment for patient diagnosis.
* The doctor/LLM has three actions: ask a question, request a test, or diagnose.
* The environment responds with real or synthetic information.
* Doctors verified 508 responses (real and synthetic): 0 leaks, 8 potentially problematic.
* Build a multi-agent system: **MAI-Dx Orchestrator**
* Prompt-tuned with GPT-4.1 and tested with O3.
* **Dr. Hypothesis**: Proposes diagnoses.
* **Dr. Test-Chooser**: Assigns tests.
* **Dr. Challenger**: Verifies/rethinks the approach.
* **Dr. Stewardship**: Optimizes cost.
* **Dr. Checklist**: Ensures the correct format.
* **QUESTION**: How do the agents debate? Is there a **MAIN** agent for handoffs? Or is this written in the workflow?
## [Results](https://astro-blog-bice-chi.vercel.app/blog/sequential-diagnosis#results)
Baselines:
* Different models with a very basic prompt that **DOES NOT ASK THEM TO MINIMIZE COST**. The study still measures estimated test costs.
* Primary physician and generalist… **NO SPECIALIST**, **NO EXTERNAL RESOURCE** (books/internet).
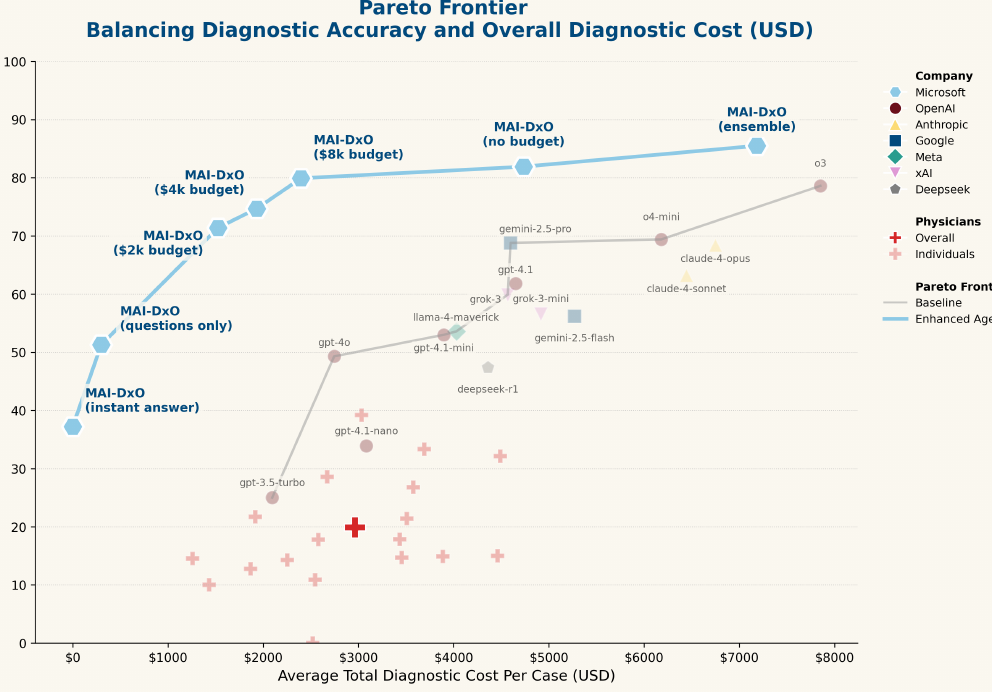
Source: [2506.22405v1, Figure 7, PDF p. 13](https://arxiv.org/pdf/2506.22405v1#page=13). Re-extracted from the cited paper for this discussion; the original attachment is unavailable.
## [Criticisms](https://astro-blog-bice-chi.vercel.app/blog/sequential-diagnosis#criticisms)
1. **NOT A GOOD REFLECTION** on the ability/cost trade-off.
* **NO MENTION** about **COST** in the [base prompt](https://astro-blog-bice-chi.vercel.app/blog/sequential-diagnosis#prompt) → not a very well-calibrated result.
* Figure 8 perhaps gives a better comparison of **UPPER-BOUND ABILITY**.
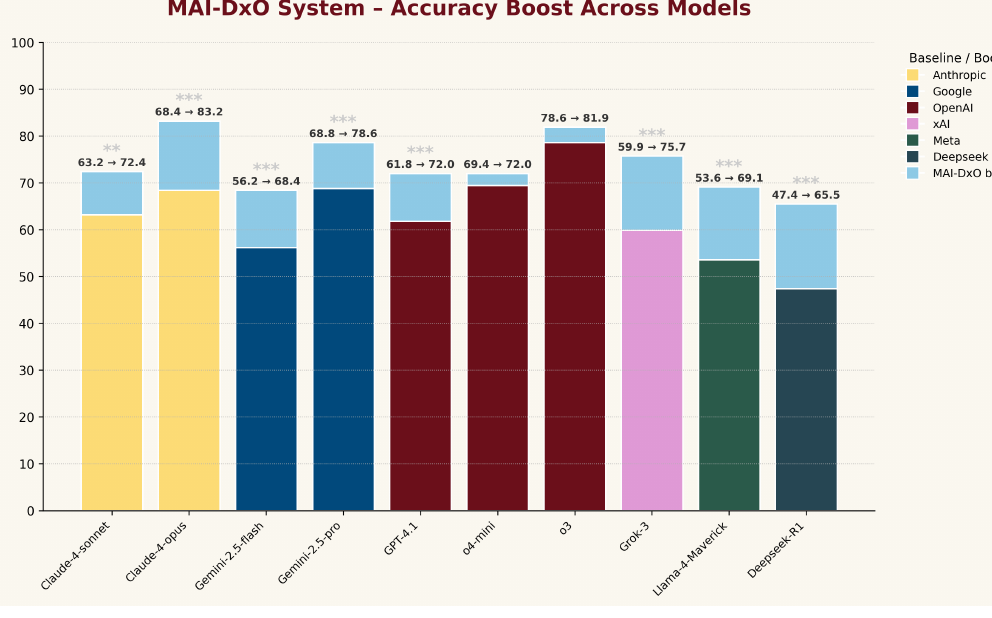
Source: [2506.22405v1, Figure 8, PDF p. 15](https://arxiv.org/pdf/2506.22405v1#page=15). Re-extracted from the cited paper for this discussion; the original attachment is unavailable.
2. The setting is a little biased.
* Tests often take time. Doctors often order tests based on eliminating an emergency instead of finding a diagnosis; it’s a “minimize regret vs. maximize outcome” trade-off.
Base prompt
```
You are a diagnostic assistant. Order tests and ask patient questions
to determine the diagnosis.
To order tests, use tags:
CBC
Chest X-ray
...more tests...
You can also ask questions directly (make sure to put each question in
a separate tag):
Question for the patient: What are your symptoms?
Question for the patient: What is your medical history?
...more questions...
You cannot mix and tags in the same turn; just use all
tags or all tags.
Make sure to ask for enough questions and tests to reach a diagnosis.
When ready to diagnose, use tags:
Your diagnosis here
```
### [Additional Criticisms](https://astro-blog-bice-chi.vercel.app/blog/sequential-diagnosis#additional-criticisms)
> A doctor shares similar concerns[^1]
1. Used **ZERO** healthy patients.
2. “Cost-effective” ignores **HUMAN TOLL**.
3. The physician comparison is “**RIGGED**” (too many restrictions).
4. The “Retrospective Oracle” Problem (tests are solved, but not all tests in real life are solvable).
5. **NO “TIME-TO-STOP”**. Great doctors know when **NOT** to test.
## [Outlook](https://astro-blog-bice-chi.vercel.app/blog/sequential-diagnosis#outlook)
1. The **Orchestrator** should be compared against:
* A single agent with detailed instructions.
* A multi-shot agent.
* Division among specialists is **NOT NECESSARY**.
2. Test against noisy information; the vignette seems **TOO IDEALISTIC**.
* The MedPAIR[^2] reveals that LLMs (non-thinking) are very sensitive to the vignette and have a tendency to jump to a conclusion with **WRONG EVIDENCE**.
3. Test against easier/more common cases.
4. Test against safety.
Sources & further reading
## References
[^1]: Dr. Dominic Ng: [https://x.com/DrDominicNg/status/1939816655829475648](https://x.com/DrDominicNg/status/1939816655829475648)
[^2]: MedPAIR: Measuring Physicians and AI Relevance Alignment in Medical Question Answering: [https://arxiv.org/pdf/2505.24040](https://arxiv.org/pdf/2505.24040)